
🧠 DeepSeek-V3.2-Speciale: The Reasoning Powerhouse
A revolutionary AI model that surpasses GPT-5 and matches Gemini-3.0-Pro in advanced reasoning capabilities
🏆 Unmatched Reasoning Performance
DeepSeek-V3.2-Speciale surpasses GPT-5 and matches Gemini-3.0-Pro in reasoning capabilities while achieving gold-medal performance in prestigious competitions including IMO and IOI 2025, setting a new standard for AI problem-solving.
⚙️ Advanced Architecture
Features a massive 685 billion parameters with proprietary DeepSeek Sparse Attention (DSA) technology that dramatically reduces computational complexity while maintaining exceptional performance across 128K token contexts.
🔍 Reasoning-First Design
Specialized reasoning-first architecture deliberately eliminates tool-calling functionality to maximize pure inference capabilities for complex mathematical and logical problems, focusing entirely on deep reasoning.
📊 Performance Trade-offs
Requires higher token usage than standard models but delivers superior performance on olympiad-level problems and complex reasoning tasks, making it ideal for advanced scientific and mathematical applications.
⚡ Revolutionary Efficiency
DSA technology enables near-linear computational complexity for long contexts, making it significantly more efficient than traditional transformer models at scale and allowing for deeper reasoning with less computational overhead.
🔒 Focused Availability
Available exclusively through API access, ensuring focused community evaluation and research on its advanced reasoning capabilities while maintaining quality control over this specialized AI system.
The AI That’s Beating GPT-5 at Complex Problem-Solving (And It’s 5x Cheaper)
Imagine an AI model that solves math problems at Olympiad level, writes code like a world-class programmer, and costs a fraction of what you’d pay for GPT-5. That’s not science fiction—that’s DeepSeek V3.2-Speciale, the new reasoning model that quietly launched in late November 2025 and is already reshaping how teams approach expensive AI operations.
If you work with AI—whether for content creation, coding, data analysis, or research—this changes everything. DeepSeek V3.2-Speciale isn’t just another model competing for attention. It’s genuinely outperforming closed-source giants like GPT-5 High and Gemini 3.0 Pro on specialized reasoning tasks, achieving gold-medal performance in international math and coding competitions, and it’s available free through their chat interface or incredibly cheap through their API. For indie creators, startups, and enterprises watching their AI budgets spiral out of control, this is the moment to pay attention.
Let’s break down what makes this model tick, how it stacks up against the competition, and how you can start using it today—without breaking the bank.
What Exactly Is DeepSeek V3.2-Speciale? Understanding the Reasoning Revolution
DeepSeek V3.2-Speciale is what happens when you take a 685-billion-parameter AI model and supercharge it with ten times more computational training focused on pure reasoning. Think of it like this: if regular AI models are like calculators, reasoning models like this one are like hiring a genius mathematician who thinks through every step of a problem before answering.
The key innovation here is **DeepSeek Sparse Attention (DSA)**—a clever mechanism that lets the model focus only on the most relevant parts of your text instead of analyzing every single word relationship. In practical terms, this means it can handle up to 128,000 tokens (roughly 300-400 pages of text) without the cost and speed penalties that usually come with long documents.
The “Speciale” part matters too. There are actually two variants of V3.2: the base model that balances general usefulness with reasoning power, and then Speciale—the specialized version that trades tool-use capabilities for absolutely maxed-out reasoning abilities. It’s like choosing between a Swiss Army knife and a precision scalpel. You lose some features, but what remains works with Olympic-level precision.
The Gold-Medal Achievement: Why Benchmarks Actually Matter Here
Here’s where things get genuinely impressive. In November 2025, the International Mathematical Olympiad (IMO), International Olympiad in Informatics (IOI), Chinese Mathematical Olympiad (CMO), and other elite competitions tested reasoning models. DeepSeek V3.2-Speciale achieved gold-medal level performance across all of them.
What does this actually mean for you?
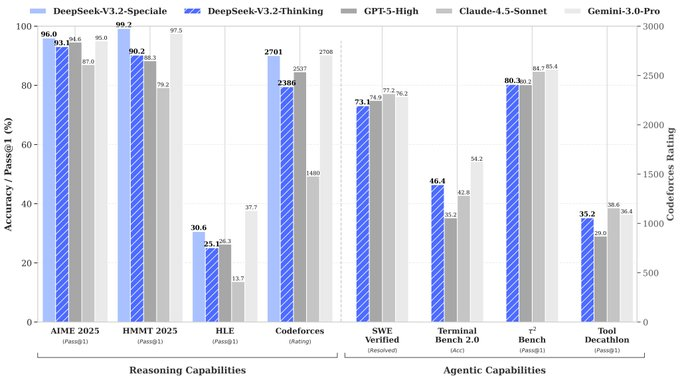
📌 On AIME 2025 (American Invitational Mathematics Examination): V3.2-Speciale scored 96.0 out of 100, beating GPT-5 High (94.6) and matching or exceeding Gemini 3.0 Pro (95.0).
📌 On SWE-Verified (software engineering problems): It achieved 73.1%, proving it can actually debug and fix real code in verified production environments—not just generate perfect-looking code snippets.
📌 On Codeforces (competitive programming platform): Thinking mode reached a 2708 rating, outpacing Gemini 3.0 Pro’s 2537. This means it genuinely solves harder algorithmic problems faster.
These aren’t cherry-picked numbers from a vendor’s marketing slide. These are standardized, peer-reviewed benchmarks that developers, researchers, and enterprises use to make real decisions. The model is legitimately world-class at hard thinking tasks.
The Cost Revolution: How DeepSeek Slashed Prices Without Slashing Quality
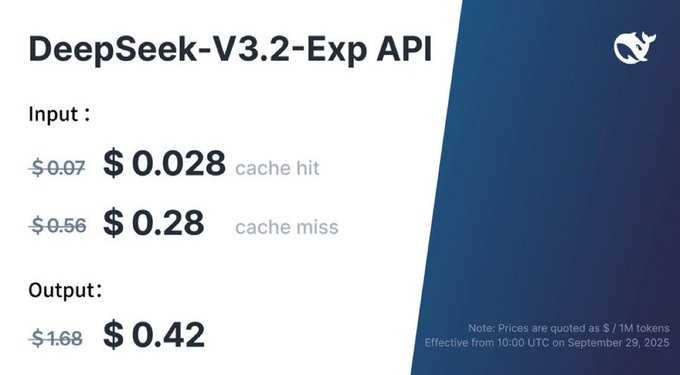
This is where the value story really hits home. Here’s the API pricing showdown:
| Model | Input (per 1M tokens) | Output (per 1M tokens) | How Much Cheaper? |
|---|---|---|---|
| DeepSeek V3.2-Speciale | $0.28 | $0.42 | Baseline |
| GPT-5 High | $1.25 | $10.00 | 18-24x more expensive |
| Gemini 3.0 Pro | $3.50 | $14.00 | 8-33x more expensive |
| Claude Opus | $15.00 | $75.00 | 35-180x more expensive |
To put this in rupees: a million input tokens on GPT-5 costs about ₹10,400 ($1.25 per token after conversion). The same 1 million tokens on DeepSeek? About ₹235 ($0.28). That’s roughly 44x cheaper in INR terms.
How did DeepSeek pull off this magic trick? The Sparse Attention mechanism. Traditional AI models treat every word relationship equally, creating squared computational costs as context length grows. DeepSeek’s system cherry-picks only the important tokens, cutting compute requirements in half while maintaining quality. It’s like switching from reading every sentence in a 400-page book to a smart summary that hits all the important points.

The Open-Source Advantage: Full Control, Zero Lock-In
Here’s a detail that matters more than most people realize: DeepSeek V3.2-Speciale is completely open-source under the MIT License. This means you can:
✅ Download the model weights and run it on your own servers with zero restrictions
✅ Modify it for your specific industry or use case
✅ Use it commercially without paying licensing fees
✅ Keep your data private (no cloud dependency)
✅ Deploy it in regulated environments like healthcare or finance where cloud-only solutions get rejected
GPT-5 and Gemini? Both proprietary. You’re renting access, not owning capability. With DeepSeek, you own the entire stack. For content creators using Make.com automations, developers building custom API integrations, and teams working in sensitive industries, this open approach removes entire categories of risk and expense.
The MIT License specifically allows commercial use without any special agreements or revenue sharing—you just need to include the license notice.
How to Actually Use DeepSeek V3.2-Speciale: Two Dead-Simple Paths
Path 1: Free Web Chat (Zero Setup Required)
👉 Visit chat.deepseek.com
The latest V3.2-Exp model is available instantly in a clean web interface. No account required, no tokens needed—just type your question. This is perfect for trying it out, brainstorming, debugging code snippets, or working through complex reasoning problems.
Path 2: API Access (For Serious Volume)
For developers, automations, and production workflows, you’ll want the API. Here’s the process:
Sign up at api.deepseek.com and add credits (you can start with as little as $5 USD or ₹415)
Get your API key from your account dashboard
Make your first request using Python, JavaScript, or any language with HTTP support: