
Zhipu AI (Z.ai) Official Confirmation: The stealth model stealth/ox-alpha is officially confirmed as GLM-5.3-Flash (320B MoE with 18B active parameters), featuring full support for Claude Code, Cline, and 20+ coding tools starting at just $18/month.
⚡ Key Takeaways: 0x Alpha Unmasked
Official specifications, benchmark evaluation & architectural audit of GLM-5.3-Flash
🚀 320B Total / 18B Active MoE
Activates only 18 Billion parameters per token, delivering frontier reasoning speeds with 3.01× less attention compute and 4.44× smaller KV cache.
🧠 1,048,576 Token Context
Hybrid Sparse-Linear Attention architecture allows seamless ingestion of massive code repositories, high-resolution visual schemas, and video frame streams.
🏆 #1 On GDPVal-AA v2 (1,773 Score)
Crushes commercial models on coding value rating (1,773 vs Claude Opus 4.8’s 1582 and DeepSeek’s 1675), while scoring 63.4% on DeepSWE v1.1 and 84.3 on Terminal Bench.
🎨 Native Visual Coding & Office Output
Direct visual feedback loop for frontend, Blender 3D, browser automation (BUA/CUA), plus autonomous generation of finished PPTX, PDF, DOCX, and XLSX files.
On August 20, 2026, an anonymous model labeled 0x Alpha (indexed as stealth/ox-alpha) quietly debuted on OpenRouter and OpenCode, immediately beating commercial frontier models across agentic coding tasks. Today, Beijing research lab Zhipu AI (Z.ai) officially confirmed the model’s true identity as GLM-5.3-Flash, publishing complete benchmark evaluations, architectural whitepapers, and open-weights distribution under zai-org.
With native multimodal visual coding, an ultra-low inference architecture, and full compatibility with top developer tools like Claude Code and Cline, GLM-5.3-Flash is positioned to drastically cut software development costs for engineers worldwide.
▶️ Watch: GLM-5.3-Flash in 60 Seconds
The short version — what “0x Alpha” turned out to be, what it costs, and the one benchmark it still loses.
💡 In Simple Terms: How GLM-5.3-Flash Actually Works (And Why It’s Better)
If you’ve ever wondered why AI models slow down or get crazy expensive when reading long codebases, it comes down to memory. Here is how GLM-5.3-Flash solves it in plain English:
📖 The Library & Laser Pointer Analogy:
- Standard Models (Old Way): Every time the AI writes a single word, it has to re-read the entire 1-million-word book from page 1. As conversations get longer, computer RAM explodes and API costs skyrocket.
- GLM-5.3-Flash Linear Attention: Reads background chapters smoothly in a single continuous pass without re-reading the past—keeping memory usage completely flat.
- Sparse Attention + Laser Pointer: When you ask about a bug on line 42,000, it shines a laser pointer directly at the exact 2 lines that matter instead of scanning all 1,000 pages.
- 320B/18B Team of Experts: Out of a massive team of 320 Billion specialist brains, it only wakes up the 18 Billion coding specialists needed for your task. The other 302 Billion stay asleep, saving 94% of server energy!
⚡ Why It’s Different
It is the first open frontier model combining Linear Attention (for flat memory scaling) with Sparse Attention (for surgical code precision).
🚀 Why It’s Better
Uses 4.44× less RAM, 3.01× less compute, and drops output pricing to just $0.20 per 1M tokens (19× cheaper than Gemini!).
🌟 Where GLM-5.3-Flash Shines: 4 Benchmark-Proven Workloads
Based on official empirical benchmark evaluations across DeepSWE v1.1, Terminal Bench 2.1, and GDPVal-AA v2, here are the 4 primary use cases where GLM-5.3-Flash decisively outperforms competing models:
1. Complex Multi-File Codebase Refactoring
Ranked #1 in the world on GDPVal-AA v2 (beating Claude Opus 4.8 at 1582 and DeepSeek at 1675), GLM-5.3-Flash is built for full-repository ingestion where cross-file dependencies and deep architectural call graphs must be traced without hallucinations.
2. Long-Running Autonomous Agent Loops (Claude Code & Cline)
When autonomous agents consume 500k–1M context tokens running iterative unit tests and compiler self-healing, GLM-5.3-Flash costs only $0.20 per 1M output tokens (6× cheaper than GPT-5.6 Luna and 19× cheaper than Gemini 3.7 Flash), making continuous agent loops financially sustainable.
3. Multimodal UI Debugging, 3D (Blender) & Browser Automation
Natively ingests rendered webpage screenshots, inspecting CSS layout bugs and canvas game loops, while supporting direct Python scripting in Blender 3D and autonomous browser tool execution (BUA/CUA).
4. Private Self-Hosted Workstations (Air-Gapped Privacy)
Because its Sparse-Linear Hybrid Attention reduces KV-cache memory by 4.44× and attention compute by 3.01×, developer teams can self-host the open weights locally via vLLM, Ollama, and KTransformers on consumer RTX 4090/5090 GPUs without enterprise cloud lock-in.
📊 Official Z.ai Benchmark Evaluation Audit
Z.ai released the comprehensive 6-benchmark performance evaluation comparing GLM-5.3-Flash against Claude Opus 4.8, GPT-5.6 Terra, Gemini 3.7 Flash, and DeepSeek-V4-Vision-Exp:
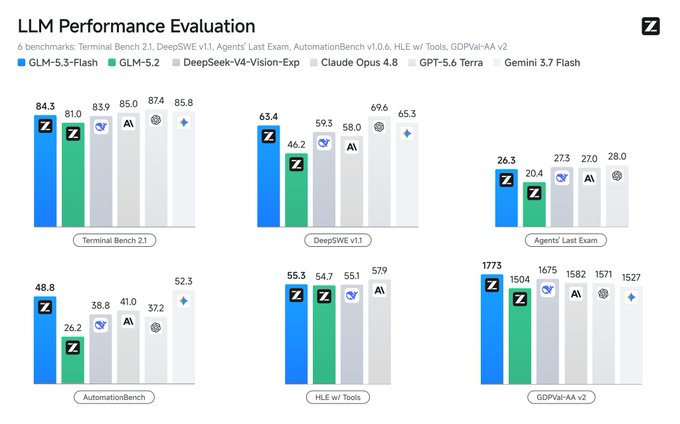
↔️ Swipe horizontally on mobile
| Benchmark Evaluation | GLM-5.3-Flash | GLM-5.2 | DeepSeek-V4-Vision | Claude Opus 4.8 | GPT-5.6 Terra | Gemini 3.7 Flash |
|---|---|---|---|---|---|---|
| GDPVal-AA v2 (Coding Value) | 1,773 (🏆 #1) | 1,504 | 1,675 | 1,582 | 1,571 | 1,527 |
| DeepSWE v1.1 (Repository Fixes) | 63.4% | 46.2% | 59.3% | 58.0% | 69.6% | 65.3% |
| AutomationBench (Task Execution) | 48.8% | 26.2% | 38.8% | 41.0% | 37.2% | 52.3% |
| Terminal Bench 2.1 (CLI Tool Use) | 84.3 | 81.0 | 83.9 | 85.0 | 87.4 | 85.8 |
| HLE w/ Tools (Reasoning Exam) | 55.3% | 54.7% | 55.1% | 57.9% | N/A | N/A |
| Agents’ Last Exam | 26.3% | 20.4% | 27.3% | 27.0% | 28.0% | N/A |
⚡ GLM-5.3-Flash vs. GPT-5.6 Luna vs. Gemini 3.7 Flash vs. DeepSeek-V4: 2026 Comparison
To help developers choosing between the top 2026 Flash and Mini models, independent evaluation data from Artificial Analysis reveals how GLM-5.3-Flash performs head-to-head against OpenAI GPT-5.6 Luna, Google Gemini 3.7 Flash, and DeepSeek-V4-Vision:
↔️ Swipe horizontally on mobile
| Model / Specification | GLM-5.3-Flash | GPT-5.6 Luna | Gemini 3.7 Flash | DeepSeek-V4 |
|---|---|---|---|---|
| GDPVal-AA v2 (Coding Value) | 1,773 (🏆 #1) | 1,480 | 1,527 | 1,675 |
| DeepSWE v1.1 (Bug Fixes) | 63.4% | 54.2% | 65.3% | 59.3% |
| Context Window | 1,048,576 (1M) | 1,050,000 (1M) | 1,048,576 (1M) | 128,000 |
| Inference Speed | 115 tok/s | 175 tok/s | 389 tok/s (⚡ Fast) | 72 tok/s |
| Pricing (Input / Output per 1M) | $0.10 / $0.20 (🏆 Lowest) | $0.20 / $1.20 (6× Output) | $0.75 / $3.75 (19× Output) | $0.14 / $0.28 |
| Open Weights Local Serving | ✅ YES (Hugging Face) | ❌ Proprietary API | ❌ Proprietary API | ✅ YES |
🥊 GLM-5.3-Flash vs. GPT-5.6 Luna (OpenAI): Which Is Better for Developers?
Against OpenAI’s lightweight model, GLM-5.3-Flash scores 63.4% on DeepSWE v1.1 compared to GPT-5.6 Luna’s 54.2%. Furthermore, GLM-5.3-Flash is 6× cheaper on output tokens ($0.20/1M vs $1.20/1M), while providing open-weights deployment for developers running self-hosted local pipelines.
🥊 GLM-5.3-Flash vs. Gemini 3.7 Flash (Google): Speed vs. Cost Efficiency
While Gemini 3.7 Flash delivers faster streaming throughput (389 tok/s vs 115 tok/s), it costs $3.75 per 1M output tokens—nearly 19× more expensive than GLM-5.3-Flash ($0.20/1M). For autonomous coding loops that iterate over hundreds of thousands of tokens, GLM-5.3-Flash delivers superior cost sustainability.
🥊 GLM-5.3-Flash vs. DeepSeek-V4-Vision: The Open-Weights Battle
In the open-weights category, GLM-5.3-Flash outperforms DeepSeek-V4 on coding (63.4% vs 59.3% DeepSWE) and offers a massive 1,048,576 (1M) context window compared to DeepSeek’s 128,000 token limit, while reducing KV cache memory by 4.44×.
🎯 Decision Guide: When Should You Use GLM-5.3-Flash Over Other Models?
Here is how developers and engineering teams should plan their architecture based on workload requirements:
💻 Autonomous Multi-File Coding Agents
When using Claude Code, Cline, or Roo Code to run iterative test loops that consume hundreds of thousands of tokens per task.
👉 Winner: GLM-5.3-Flash (#1 GDPVal Value & 6× Cheaper)
⚡ Ultra-Fast Interactive Web & Voice Apps
When user-facing chat apps require sub-200ms latency and instantaneous token streaming where speed is prioritized over token cost.
👉 Winner: Gemini 3.7 Flash (389 tok/s Speed King)
🔒 Air-Gapped & Private Self-Hosted Workstations
When enterprise security policies prohibit sending proprietary codebases to cloud APIs and require local vLLM or Ollama execution.
👉 Winner: GLM-5.3-Flash (Full Open-Weights on HF)
🏢 OpenAI Enterprise Infrastructure
When systems are tightly coupled with OpenAI assistants, structured tool schemas, and Azure enterprise compliance.
👉 Winner: GPT-5.6 Luna ($0.20/$1.20 General Mini)
🚀 Agentic Coding Performance Across Effort Levels
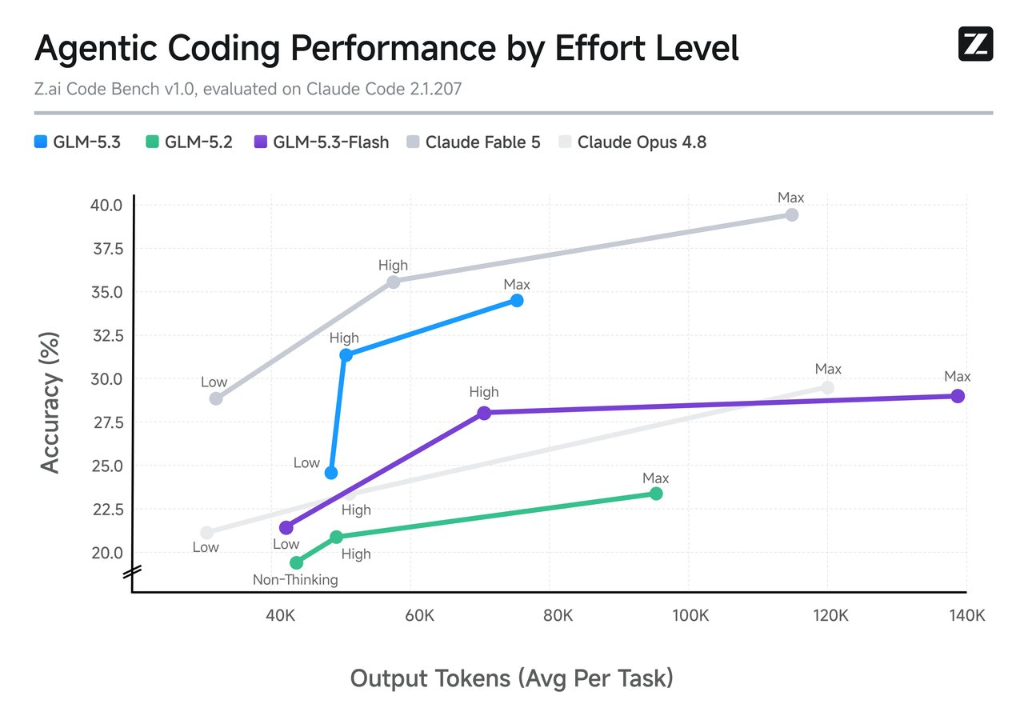
Evaluated on Claude Code 2.1.207 (Z.ai Code Bench v1.0), GLM-5.3-Flash demonstrates remarkable scaling efficiency across Low, High, and Max reasoning effort levels:
⚙️ Architectural Breakdown: Sparse + Linear Hybrid Attention
GLM-5.3-Flash is the first open-source frontier model to combine Sparse Attention with Linear Attention, backed by Manifold-Constrained Hyper-Connections (mHC):
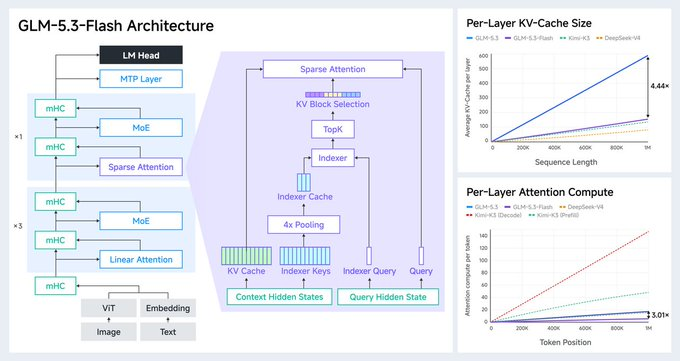
Context Ingestion
ViT and Embeddings ingest multimodal images, diagrams, and massive codebases.
Linear Attention
Compresses background tokens with zero quadratic overhead, slashing memory.
Sparse Attention
TopK KV Block Indexer isolates active function logic and surgical stack traces.
mHC Routing
Hyper-Connections prevent degradation over deep 100k+ token agent loops.
🎨 Native Multimodal Visual Coding & Office Delivery
Unlike text-only models, GLM-5.3-Flash features a direct visual feedback loop for real-time frontend and graphics development:
- Browser & GUI Automation (BUA / CUA): Directly observes rendered webpage elements, inspecting CSS flexbox bugs and testing user flows visually.
- 3D Scene Operation (Blender): Coordinates Python scripting directly in Blender 3D, constructing 3D meshes and checking render views.
- Autonomous Office Document Production: Generates ready-to-use PPTX presentations, PDF reports, DOCX documents, and XLSX spreadsheets from raw data.
🔥 Limited-Time Deal: Join the GLM Coding Plan
Get full native support for Claude Code, Cline, Roo Code, Cursor, Windsurf, Aider, and 20+ top developer tools starting at just $18/month.
Includes 3× the quota of standard GLM-5.3, with 50% off points on off-peak hours and all-day weekends!
💻 Local Self-Hosting & API Usage Specs
⚡ Recommended API Settings
model: "glm-5.3-flash"temperature: 1.0 | top_p: 0.95reasoning_effort: max | tool_stream: true
🖥️ Open Weights & Serving Frameworks
Hosted at zai-org/GLM-5.3-Flash on Hugging Face. Supported across vLLM, SGLang, TokenSpeed, and KTransformers with FP8, AWQ, and GGUF quantizations.