Qwen3.8-Flash-Next: How a 6B Active Model Beats Frontier AI on SWE-bench
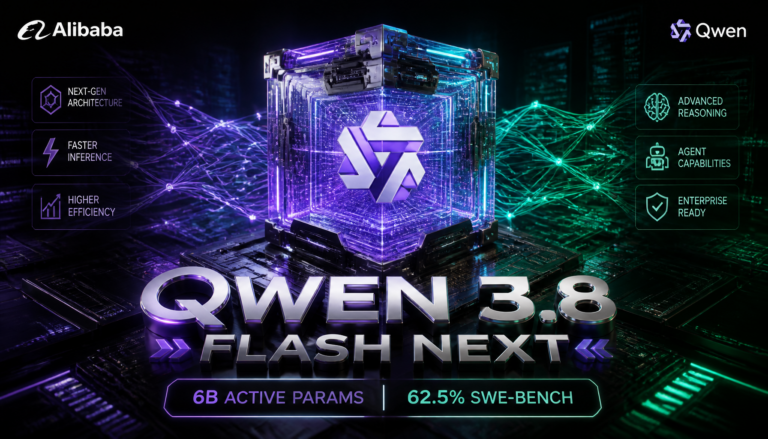
⚡ Key Takeaways at a Glance The 6B Active Parameter Paradox: Alibaba’s Qwen3.8-Flash-Next packs ~180B total parameters across a 125B MoE backbone and a 51B N-gram lookup table, but activates only ~6B parameters per token—delivering sub-210ms latency and 195 tok/s…