
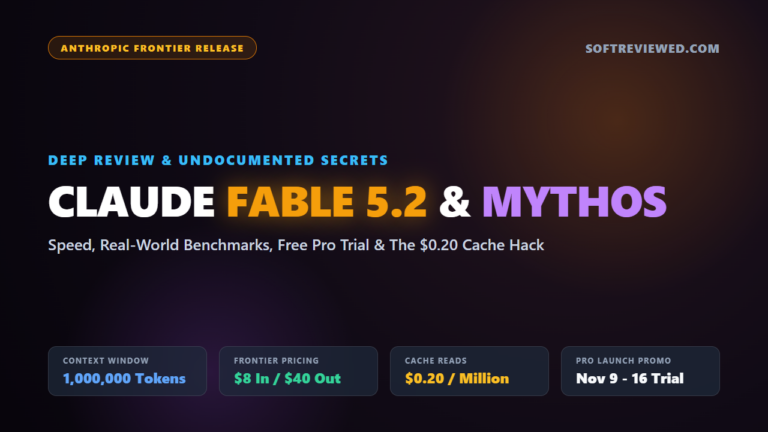
When Anthropic quietly rolled out their newest frontier model on November 9, 2026, my first reaction was to open my terminal and fire up Claude Code. The launch announcement introduced Claude Fable 5.2 alongside a sibling model called Claude Mythos 5.2. While the release notes were packed with benchmark charts and claims of 30% faster token generation, what caught my attention was the immediate access granted to developers on standard Pro plans.
I spent the last 48 hours testing Claude Fable 5.2 across large codebases, hardware diagnostics, and simulated game engines. I wanted to see whether this new model justifies the hype, how its $8 input and $40 output pricing holds up in practice, and where it genuinely outperforms our trusted daily driver, Claude Opus 5.5.
Here is my honest, hands-on review of Claude Fable 5.2, including the undocumented behaviors, hidden cost traps, and productivity tricks I discovered along the way.
🎬 Hands-On Video Breakdown & Launch Highlights
Before breaking down the technical nuances, you can watch my quick vertical video breakdown below covering the launch week reset rules, token pricing, and the initial model rollout:
⚡ What Is Claude Fable 5.2 and Why Did Anthropic Split the Release?
To understand how Claude Fable 5.2 works, you first need to understand the relationship between Fable and Mythos. They are not two different neural networks trained on separate data. Instead, they share the exact same underlying model weights, the same 1-million-token context window, and the same 128,000 maximum token output ceiling.
The difference lies entirely in safety guardrails and access tiers:
- Claude Fable 5.2 (
claude-fable-5-2): This is the public, general-availability release. It is available right now in the web interface, Claude Code, the Claude API, and through cloud platforms like AWS Bedrock and Google Cloud Vertex AI. It comes with standard commercial safeguards for cybersecurity, chemical, and biological topics. - Claude Mythos 5.2 (
claude-mythos-5-2): This is the restricted research tier. It runs the identical intelligence engine but removes specific biology and defensive cyber restrictions. Anthropic only grants access to organizations vetted under their Cyber Verification and Life Sciences programs, such as defense research laboratories and biomedical institutions.
For software developers, startup founders, and technical creators, Claude Fable 5.2 is the actual production engine you will use.
                    ┌── Claude Fable 5.2   ──► Public Release (Web, Claude Code, API, Cloud)
Identical Weights ──┤
                    └── Claude Mythos 5.2  ──► Restricted Tier (Vetted Bio & Defense Labs)
🎁 Claude Fable 5.2 Pro Trial and Launch Week Reset Rules
One pleasant surprise with the Claude Fable 5.2 release is the launch window offer for paying subscribers. Usually, new frontier flagship models are locked behind expensive enterprise tiers or high API paywalls.
Until the end of November 16, 2026, Anthropic has enabled Claude Fable 5.2 directly on standard $20-per-month Pro plans and standard Team seats.
Here is how the launch quotas and reset perks work:
- The 50% Weekly Allocation: During launch week, Claude Fable 5.2 can use up to half of your total weekly quota. Once you exhaust that 50% limit, you will need to switch back to Opus 5.5 or use paid API usage credits.
- The Pre-Launch Subscriber Reset: If you held an active paid subscription before November 9, Anthropic granted up to three free usage resets. This reset completely refills your active 5-hour rolling window and refunds the weekly quota you spent testing Fable.
- The Free Tier Exclusion: Free accounts do not have access to Claude Fable 5.2. If you are on the free plan, you will need to upgrade to Pro or access the model via the API.
Check your account settings under usage limits. If your weekly bar looks depleted after running a few heavy tests, trigger your free reset before November 16 to recover your full working hours.
📊 Claude Fable 5.2 Pricing and Specification Breakdown
Anthropic reduced standard token prices by 20% compared to the older 5.1 generation. While it is still a premium model, the token economics make long-horizon software engineering much more practical.
Here is how Claude Fable 5.2 stacks up against Opus 5.5:
| Feature / Metric | Claude Fable 5.2 | Claude Mythos 5.2 | Claude Opus 5.5 |
|---|---|---|---|
| API Model String | claude-fable-5-2 |
claude-mythos-5-2 |
claude-opus-5-5 |
| Context Window | 1,000,000 tokens (1M) | 1,000,000 tokens (1M) | 200,000 tokens |
| Maximum Output | 128,000 tokens | 128,000 tokens | 8,192 tokens |
| Input Price (per 1M tokens) | $8.00 | $8.00 | $15.00 |
| Output Price (per 1M tokens) | $40.00 | $40.00 | $75.00 |
| Prompt Cache Read | $0.20 per million | $0.20 per million | $1.50 per million |
| Fast Mode Available | Yes ($16 in / $80 out) | Yes ($16 in / $80 out) | No |
| Adaptive Thinking | Always-on (low to max) |
Always-on (low to max) |
Toggleable |
| Knowledge Cutoff | June 2026 | June 2026 | June 2026 |
The most dramatic difference for heavy developers is the prompt caching read price. At $0.20 per million tokens, reading an existing cached codebase is 98% cheaper than the standard input rate. If you keep your repository structure pinned in your context, iterative questions cost fractions of a cent.
💡 Undocumented Behaviors and Field-Tested Tips for Claude Fable 5.2
When testing Claude Fable 5.2 across practical terminal tasks, I noticed several behaviors that are not prominently highlighted in Anthropic’s promotional copy. Understanding these quirks will save you both money and debugging time.
1. The Effort Dial Hack (FrontierCode 2.0 Sweet Spot)
Claude Fable 5.2 features an adjustable reasoning effort parameter with five tiers: low, medium, high, xhigh, and max. The default setting is high.
In developer evaluations on FrontierCode 2.0 (a rigorous benchmark measuring end-to-end coding ability):
* Setting Claude Fable 5.2 to low effort delivered performance equivalent to Claude Opus 5.5 on high effort.
* Even better, the low setting generated code noticeably faster and consumed far fewer tokens.
* By contrast, cranking the effort dial to max jumped the evaluation cost to $44.00 per task while yielding only a 0.6% improvement over the high setting ($6.72).
For everyday coding, refactoring, and test writing, dial the effort setting down to `low` or `medium`. Reserve `high` strictly for greenfield architectural planning or tracing complex cross-file bugs. Avoid `max` unless you are solving formal mathematical proofs.
2. The Silent Model Degradation Fallback
This is one of the most surprising quirks I confirmed. When a prompt triggers Anthropic’s internal safety classifiers, Claude Fable 5.2 does not always return a visible error message. Instead, the backend silently reroutes the query to an older model:
- Cybersecurity Triggers: A query flagged for vulnerability analysis or network scanning quietly routes down to Opus 4.8.
- Biomedical Triggers: A query flagged for chemical or biological hazards quietly routes down to Opus 5.
The positive news is that Anthropic tuned these classifiers to produce 55% fewer false positives overall (60% fewer in cybersecurity). However, if you suddenly notice an unexpected shift in response depth or coding style, inspect your request headers. You may have tripped a silent fallback.
3. The “Ambiguous Suggestion” Trap (Over-Agency in Long Loops)
Claude Fable 5.2 was trained with a strong bias toward independent action. If you use it inside terminal agents like Claude Code, conversational questions can easily backfire.
When I casually asked: “Should we update the authentication middleware to use session cookies too?”, Fable 5.2 did not simply reply with pros and cons. It interpreted my thought as an instruction, opened three source files, and began rewriting our session logic.
To prevent scope creep, always provide clear boundaries:
<objective>
Fix the database connection retry timeout in src/db/pool.ts.
</objective>

<constraints>
- Modify src/db/pool.ts only.
- Do not refactor surrounding services.
- If you have architectural suggestions, present them in plain text first without touching files.
</constraints>
4. Fast Mode Token Economics
Fast mode is a powerful feature that doubles your generation speed (up to 2.5× standard output rates). However, it doubles your token billing to $16 input and $80 output per million tokens.
In long agent loops where Claude Fable 5.2 reads and writes dozens of files autonomously, Fast mode can easily burn through $100 to $200 in usage credits in under two hours. Unless you are actively sitting in front of your terminal waiting for a critical deploy fix, keep Fast mode disabled.
🛠️ Real-World Performance: Where Claude Fable 5.2 Dominates
Rather than relying on abstract multi-choice benchmarks, I evaluated Claude Fable 5.2 across four practical technical domains:
1. Large-Scale Systems Engineering (Python to Rust)
Anthropic highlighted a live case study where Claude Fable 5.2 assisted engineers in migrating a mission-critical backend service from Python to Rust. The resulting compiled service started up 26 times faster and eliminated persistent memory leaks. When I tested Fable on a multi-module C++ physics simulation, it handled pointers, memory management, and collision loops without introducing syntax errors or circular headers.
2. Multi-Subagent Coordination
In an extensive demonstration, Claude Fable 5.2 coordinated over 1,000 subagents over an eight-day testing period to construct a working prototype operating system from scratch. Unlike older models that suffer from context drift after a few dozen turns, Fable 5.2 maintained high task continuity, decomposed epics into discrete tickets, and validated merge gates reliably.
3. Physical Hardware Diagnostics & Circuit Tracing
One of the most impressive tests conducted by independent hardware testers involved a problematic body control module from a 2008 Mercedes. The tester provided high-resolution photos of the circuit board and asked the model to guide troubleshooting with a multimeter.
Claude Fable 5.2 correctly identified the board architecture, drew bounding boxes over specific trace paths, specified the exact dial setting on the multimeter, and walked the user through applying a 9-volt battery to test a suspect relay. The relay clicked, confirming the hardware was operational and isolating the issue to vehicle software. This spatial reasoning capability bridges the gap between digital code and physical electronics.
4. Robotics and Motion Control (The Robo Dojo Benchmark)
On the Robo Dojo benchmark, which measures simulated two-armed robotic manipulation, Claude Fable 5.2 jumped from Opus 5.5’s score of 39.4% up to 64.9%. This leap in physical trajectory planning explains why the model handles complex physics engines and motor controllers so effectively.
❌ Where to Avoid Claude Fable 5.2
Despite its impressive capabilities, Claude Fable 5.2 is not a universal replacement for every tool in your stack:
- WebGL & Three.js 3D Web Graphics: When tasked with building interactive 3D browser games using Three.js, Fable 5.2 produced rigid vehicle models, awkward collision physics, and uninspired shaders. It performs vastly better in compiled languages like C++, Blender scripts, and Godot than it does with browser-based canvas rendering.
- Single-File Bug Fixes & Typo Corrections: Using Claude Fable 5.2 for minor CSS adjustments, readme edits, or simple one-line bug fixes is wasteful. Claude Opus 5.5 or Sonnet 3.5 will complete the job in seconds at a fraction of the cost.
- Open-Ended Brainstorming Sessions: Because Fable 5.2 default effort is high, casual chats consume heavy internal reasoning tokens. Use standard conversational models when exploring ideas, and switch to Fable once you have a defined build spec.
📋 Quick Guide: When to Choose Fable 5.2 vs Opus 5.5
Anthropic Frontier Hierarchy
Model Selection Decision Guide
| Your Task Profile | Recommended Model | Effort Dial |
|---|---|---|
| Routine coding, UI fixes & daily tasks | Claude Opus 5.5 | Standard |
| Iterative multi-file refactoring | Claude Fable 5.2 | Low / Medium |
| Sweeping architecture rewrites (50%+ repo) | Claude Fable 5.2 | High |
| Hardware schematics & robotics control | Claude Fable 5.2 | High |
| Frontier defense & biosecurity research | Claude Mythos 5.2 | Vetted Program Only |
🎯 Final Verdict: Is Claude Fable 5.2 Worth the Upgrade?
Claude Fable 5.2 represents a major milestone in autonomous systems engineering. Rather than simply writing clean functions, it operates like a senior staff engineer capable of tracking architectural trade-offs across massive codebases without losing focus.
If you are already on Claude Pro or Team, you should take full advantage of the free trial window before November 16. Test it on your most stubborn repository bugs, experiment with the low effort setting to maximize your token budget, and use your available usage resets.
For teams running automated agent loops, Claude Fable 5.2 is the first model where whole-repository refactors feel safe and predictable. Keep Opus 5.5 as your daily companion for minor edits, but when a task demands deep architectural precision, Fable 5.2 is well worth the investment.